[Kotlin, Spring boot] Data Processing Efficiency in Search API: find Query vs. Internal Function? 🤔
Overview #
During a school project, while developing GAuth, an integrated social login service for school accounts, there was an API to search for registered users. It processed search functionality by receiving grade, class, and keyword inputs, with a requirement to search all if 0 was entered. I didn't develop this myself; a teammate did, and a question arose during the pull request and code review process.
It retrieved a list of users using findAllByState (a JPA method that fetches CREATED state, where State can be CREATED or PENDING).
Filtering was done within the application's internal logic, like if(grade != 0) users.filter{ it.grade == grade }.
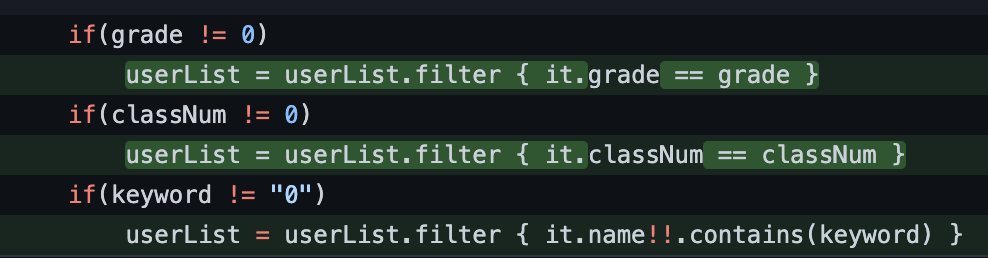
However, something felt lacking. Is it really okay to handle operations requiring many computations, such as user lists, with internal application logic? There was also the drawback that using .contains would, in the worst case, iterate users.size times.
Searching using a find query seemed better from a performance perspective. I wondered if it would be better to change the approach to perform a find based on the situation when 0 is entered, rather than going through three filtering steps.
So, the idea is to declare a function in JpaRepository and create a default function in userRepository that uses when to call different find methods when the received arguments (grade, classNum, keyword) are 0.
fun findByStateAndGradeAndClassNum(state: State, grade: Int, classNum: Int): List<User> {
        return when {
            grade == 0 && classNum == 0 -> findAllByState(state)
            grade == 0 -> findAllByStateAndClassNum(state, classNum)
            classNum == 0 -> findAllByStateAndGrade(state, grade)
            else -> findByStateAndGradeAndClassNumAndKeywordContaining(state, grade, classNum, keyword)
        }
    }
Like this.
Accordingly, methods such as findAllByStateAndClassNum, findAllByStateAndGrade, and findByStateAndGradeAndClassNumAndKeywordContaining must be declared.
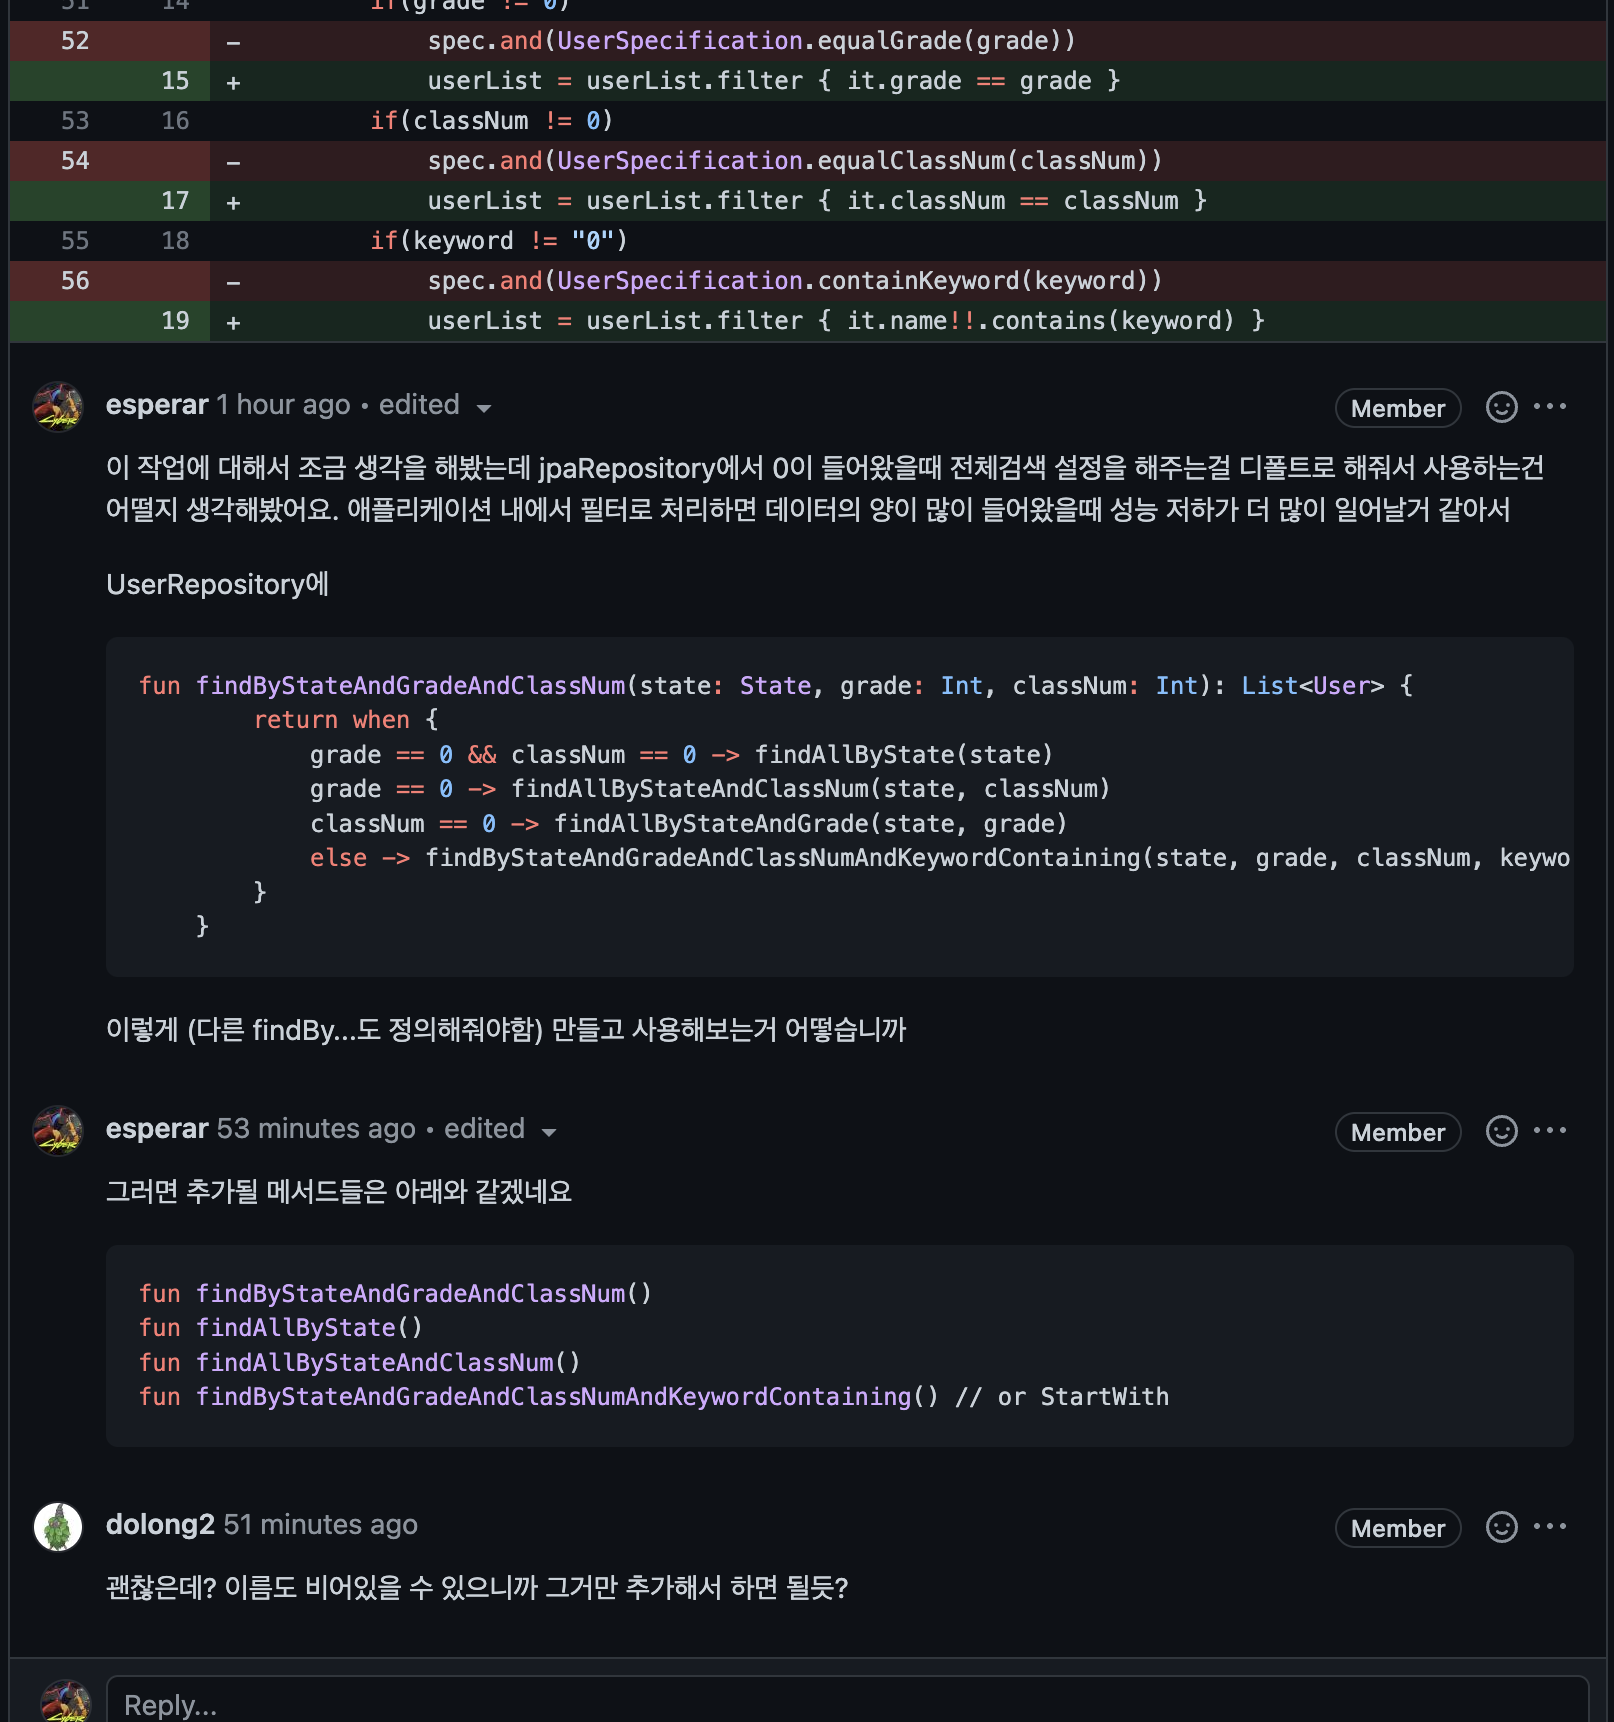
Of course, performing a find is not always unconditionally better than processing data through an internal function. This is because there are limitations to the data that can be found with find queries alone.
If complex conditions are required or there are limitations to searching data with queries alone, it seems better to use internal functions, but for most data processing tasks, performing them with find queries is preferable.
Conclusion #
The search API was implemented with an internal function, but it seems solvable with queries alone, and the code looks a bit messy.
Validation processing and corresponding
findmethods are executed in the repository class that implementsJpaRepository.findqueries seem to perform better than processing data that requires many computations.Since there are limitations to what can be done with queries alone, it seems necessary to write code appropriate for the situation.